The workflow model.
TypeLLM makes the workflow the unit of inference.
| Chat model | Decision model | Workflow model | |
|---|---|---|---|
| Purpose | Generate | Decide | Execute |
| Unit | Message | Decision | Workflow |
| Example | GPT | Jev | TypeLLM |
Switch from chat + decision model to TypeLLM
- Safer
- No out-of-schema hallucinations.
- Simpler
- No orchestration code to build or maintain.
- Cheaper
- The context is read and billed once, not once per step.
- Faster
- No round trips from multiple API calls, and independent fields run in parallel.
53%cheaper
1.9×faster
Measured on the support ticket workflow.
| Support ticket workflow | API calls | Input tokens | Time (s) |
|---|---|---|---|
| TypeLLM | 1 | 149 | 1.38 |
| Chat + decision model | 4 | 320 | 2.60 |

 dog_head

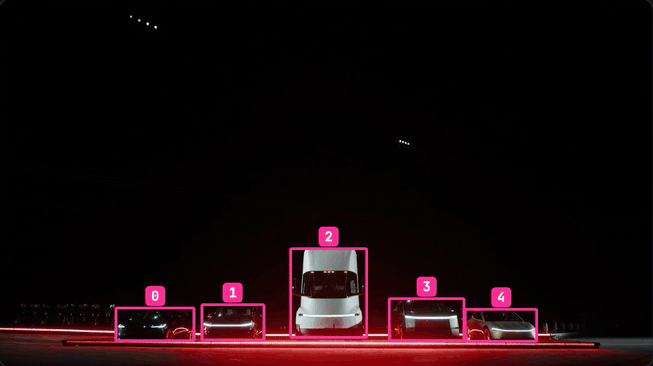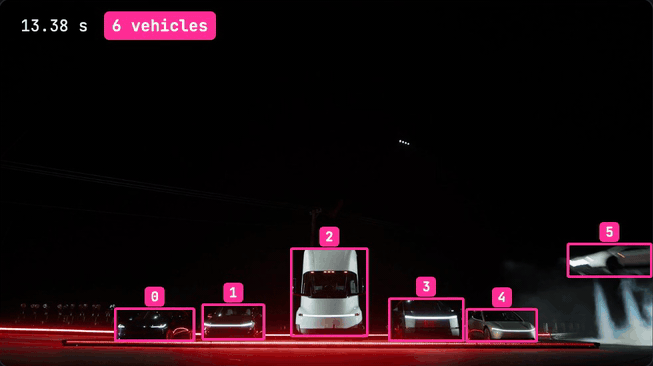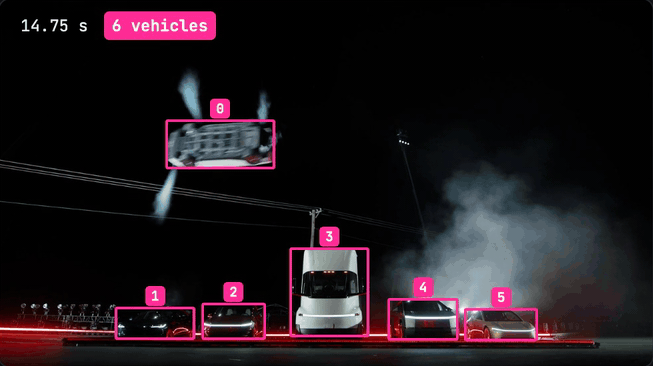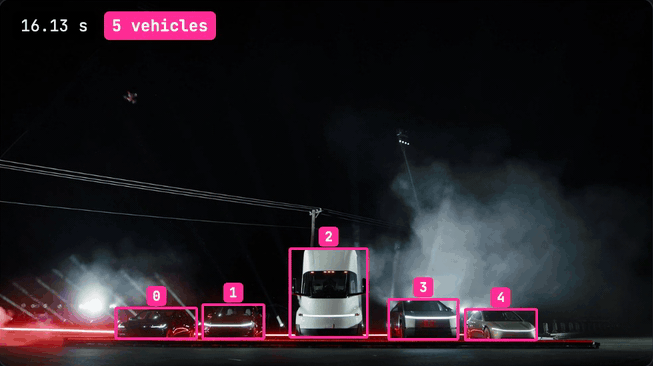 Arrays of boxesEvery match, one box each.


| Model | Type-safe output | Accuracy |
|---|---|---|
| Jev | Yes | 86.58% |
| GPT-5.6 Luna (none) | No | 89.18% |
| GPT-6 Astra (low) | No | 100.00% |
| TypeLLM (no thinking) | Yes | 84.42% |
| TypeLLM (thinking) | Yes | 98.70% |