Locate every vehicle in a video
Four seconds of a car show: a row of cars and a truck, and a car that rises into the air and flies out of the picture. Find every vehicle in every frame, each with its own box, so you can draw them, track them or count them.
Set up
Install the library:
pip install "typellm>=0.7.2" pillowGet an API key from your dashboard:
from typellm import TypeLLMClient

client = TypeLLMClient(api_key="YOUR_API_KEY")
Take the frames
TypeLLM reads images, so a video goes in as its frames. Here they are seconds 12 to 16 of the show, eight frames a second, at 1920 by 1080; the notebook downloads all 34. For your own video, take them with ffmpeg:
mkdir frames
ffmpeg -ss 12 -t 4 -i show.mp4 -vf scale=1920:-2 -r 8 frames/f%03d.jpg
import glob
import os
frames = sorted(glob.glob("frames/*.jpg"))Ask each frame for its vehicles
An array of boxes finds every match in an image, each as its top, bottom, left and right edges, from 0 to 1. Say in its instructions what counts: here the truck does, and so does a car in the air.
QUESTIONS = {
    "vehicles": {
        "type": "array",
        "items": {"type": "box"},
        "instructions": ("Every vehicle, each on its own: every car, the truck, "
                         "and any vehicle in the air."),
    },
}
Each frame is one call, and the calls run side by side:
from concurrent.futures import ThreadPoolExecutor


def locate(frame):
    response = client.generate(
        context="A frame of a video of a car show.",
        images=[frame],
        questions=QUESTIONS,
    )
    return response.result["vehicles"]


with ThreadPoolExecutor(8) as pool:
    vehicles = list(pool.map(locate, frames))
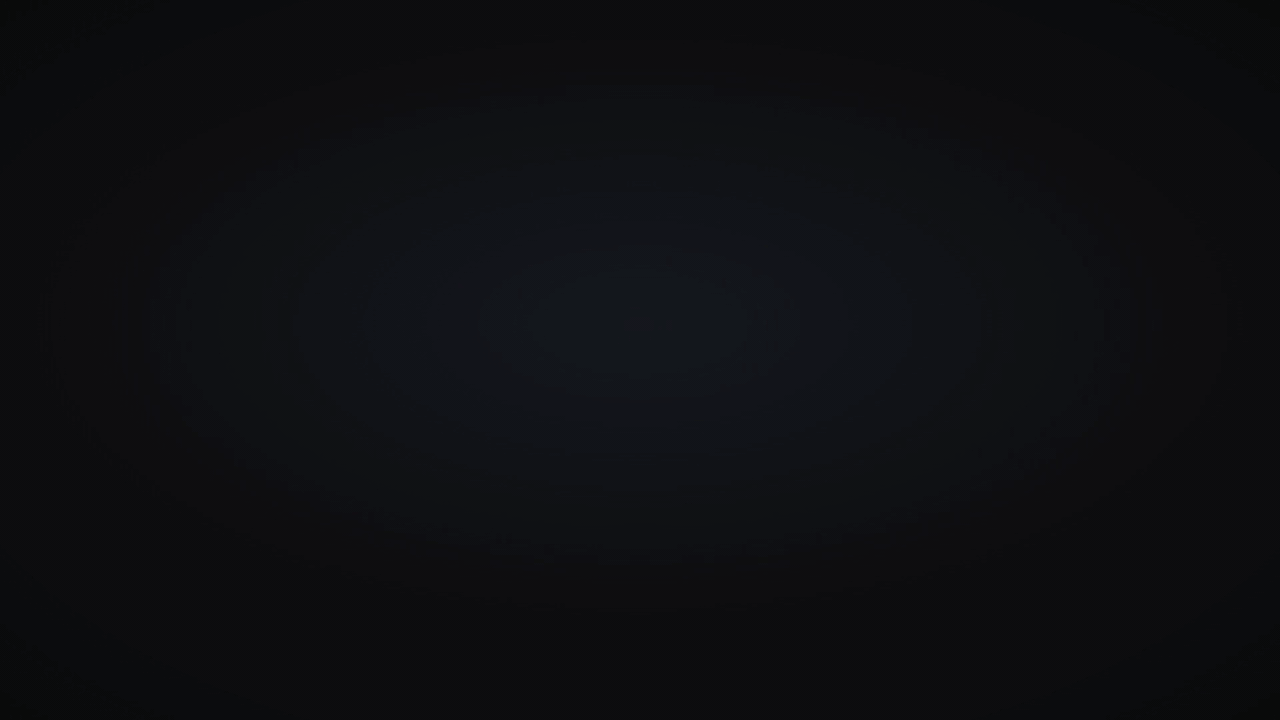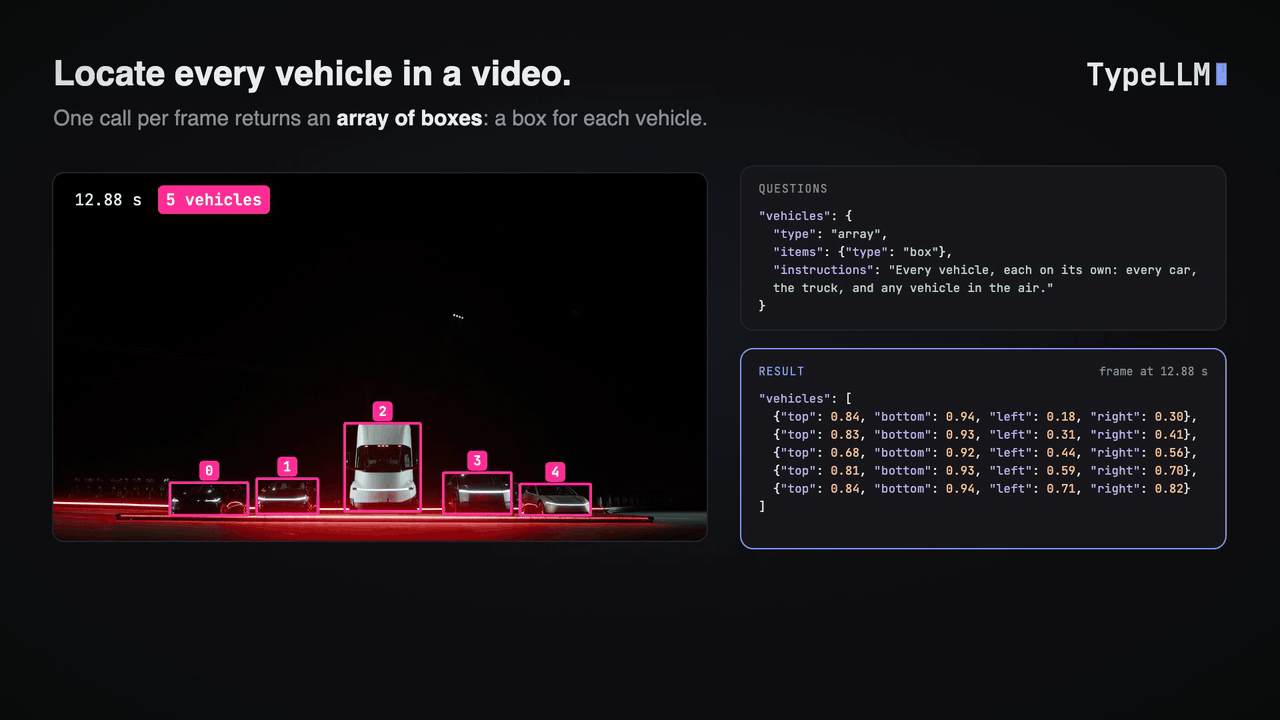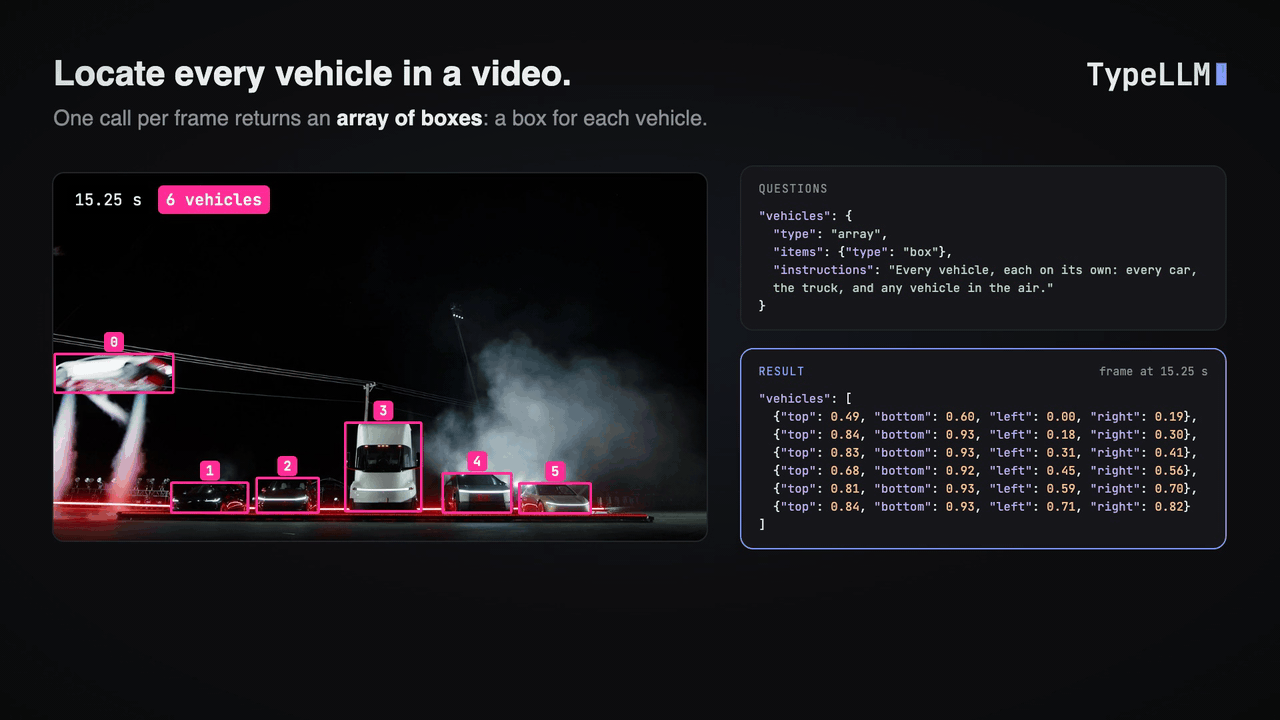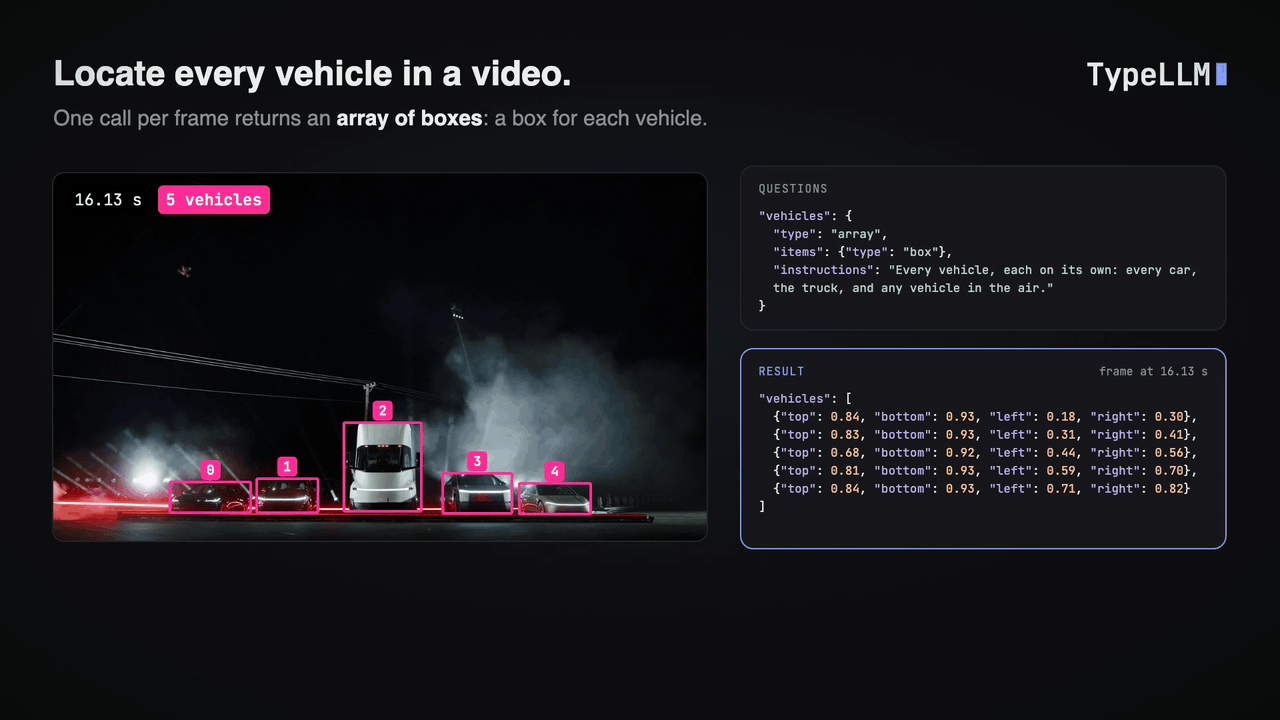
vehicles[i] is frame i's list of boxes. At 13.75 seconds, the car in the air is the last:
[{"top": 0.839, "bottom": 0.931, "left": 0.177, "right": 0.3},
 {"top": 0.827, "bottom": 0.925, "left": 0.309, "right": 0.405},
 {"top": 0.675, "bottom": 0.923, "left": 0.444, "right": 0.565},
 {"top": 0.811, "bottom": 0.931, "left": 0.597, "right": 0.705},
 {"top": 0.841, "bottom": 0.937, "left": 0.712, "right": 0.825},
 {"top": 0.493, "bottom": 0.597, "left": 0.699, "right": 0.871}]
What came back
| Seconds | Vehicles | In the frame |
|---|---|---|
| 12.00 to 13.25 | 5 | Four cars and the truck on the ground |
| 13.38 to 15.25 | 6 | A sixth rises at the right, turns over in the air and crosses to the left |
| 15.38 to 16.12 | 5 | It has flown out of the picture |
Every frame has a box for each vehicle on the ground, and one for the car in the air while it is in the picture, upside down and blurred included. Each frame read 2,096 input tokens, about $0.0001; the four seconds cost under half a cent.
Draw the boxes
The edges are fractions, so they fit the frame at any size: multiply by its width and height.
from PIL import Image, ImageDraw

os.makedirs("boxed", exist_ok=True)
for frame, boxes in zip(frames, vehicles):
    image = Image.open(frame).convert("RGB")
    width, height = image.size
    draw = ImageDraw.Draw(image)
    for box in boxes:
        edges = (box["left"] * width, box["top"] * height,
                 box["right"] * width, box["bottom"] * height)
        draw.rectangle(edges, outline=(255, 45, 149), width=4)
    image.save(os.path.join("boxed", os.path.basename(frame)))
Put them back together as an animated GIF, eight frames a second:
boxed = [Image.open(os.path.join("boxed", os.path.basename(frame))).resize((960, 540))
         for frame in frames]
boxed[0].save("boxed.gif", save_all=True, append_images=boxed[1:], duration=125, loop=0)
A frame without a vehicle comes back as [], not with a box around the nearest thing. Each frame is read on its own, so a vehicle that is hard to see in one frame can be missed there and found in the next; if you track vehicles across frames, let a vehicle missed in a single frame carry over from its neighbours. The notebook runs all of it with your key.