Read a CV into typed records
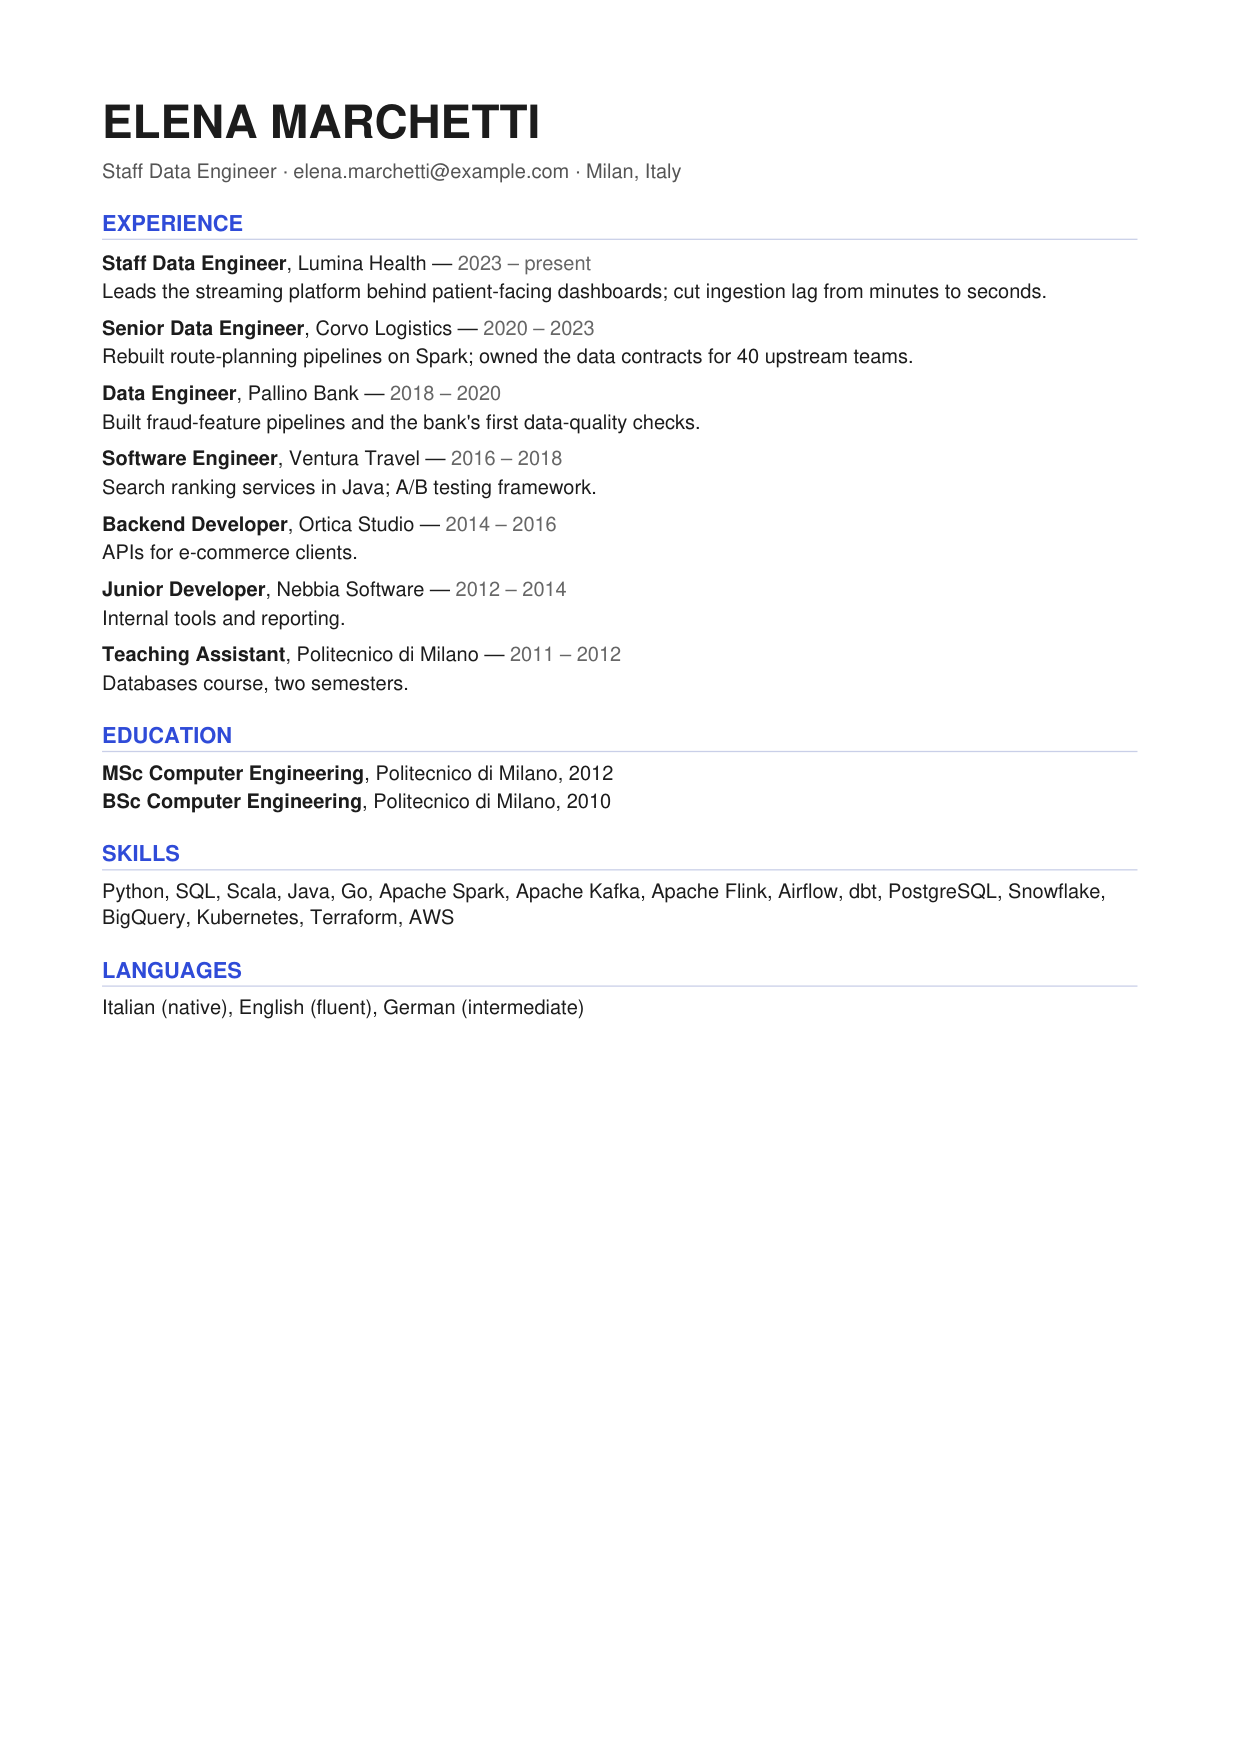
Open in playground →A CV page, sent as an image, holds one person, a varying number of jobs and a long list of skills. An object returns the candidate, an array of objects one typed record per job, and an array of strings every skill.
Challenges
- The CV is a PDF page sent as an image: the model reads the layout, not text you extracted first.
- The current job has no end year, so
end_yearisnull; every other year is an integer, not a string. - Seven jobs and sixteen skills: each array ends when no more items belong in it. The degrees and languages are not jobs or skills, so they are not in the arrays.
import os
from typellm import TypeLLMClient

client = TypeLLMClient(api_key=os.environ["TYPELLM_API_KEY"])
response = client.generate(
    context="Read the attached CV.",
    questions={
      "candidate": {
        "type": "object",
        "properties": {
          "name": {
            "type": "string"
          },
          "email": {
            "type": "string"
          },
          "city": {
            "type": "string"
          }
        }
      },
      "work_experience": {
        "type": "array",
        "instructions": "Each position on the CV, most recent first.",
        "items": {
          "type": "object",
          "properties": {
            "company": {
              "type": "string"
            },
            "title": {
              "type": "string",
              "instructions": "Job title."
            },
            "start_year": {
              "type": "integer"
            },
            "end_year": {
              "type": [
                "integer",
                "None"
              ],
              "instructions": "Year it ended; None if it is the current job."
            }
          }
        }
      },
      "skills": {
        "type": "array",
        "items": {
          "type": "string"
        },
        "instructions": "Every skill listed on the CV."
      }
    },
    images=["cv.png"],
)
print(response)Generation(
result={
'candidate': {
'name': 'ELENA MARCHETTI',
'email': 'elena.marchetti@example.com',
'city': 'Milan',
},
'work_experience': [
{
'company': 'Lumina Health',
'title': 'Staff Data Engineer',
'start_year': 2023,
'end_year': None,
},
{
'company': 'Corvo Logistics',
'title': 'Senior Data Engineer',
'start_year': 2020,
'end_year': 2023,
},
{
'company': 'Pallino Bank',
'title': 'Data Engineer',
'start_year': 2018,
'end_year': 2020,
},
{
'company': 'Ventura Travel',
'title': 'Software Engineer',
'start_year': 2016,
'end_year': 2018,
},
{
'company': 'Ortica Studio',
'title': 'Backend Developer',
'start_year': 2014,
'end_year': 2016,
},
{
'company': 'Nebbia Software',
'title': 'Junior Developer',
'start_year': 2012,
'end_year': 2014,
},
{
'company': 'Politecnico di Milano',
'title': 'Teaching Assistant',
'start_year': 2011,
'end_year': 2012,
},
],
'skills': [
'Python',
'SQL',
'Scala',
'Java',
'Go',
'Apache Spark',
'Apache Kafka',
'Apache Flink',
'Airflow',
'dbt',
'PostgreSQL',
'Snowflake',
'BigQuery',
'Kubernetes',
'Terraform',
'AWS',
],
},
thinking={},
usage=Usage(input_tokens=2232, thinking_tokens=0),
)